
Modern high-performance computing (HPC) systems power scientific discovery across fields ranging from climate modeling to artificial intelligence. Yet today's supercomputers are extraordinarily complex, combining CPUs, GPUs, high-speed networks, and sophisticated memory systems. When performance problems occur, identifying the cause can be difficult, leading to wasted computing time, higher energy consumption, and delays in research.
To address this challenge, researchers in the Performance and Energy Aware Computing Lab (PEACLab) led by Ayşe Coskun, are developing AI-powered performance analytics that help users, developers, and system operators better understand how large computing systems behave. The project transforms vast amounts of monitoring and profiling data into actionable insights. Machine learning methods are used to detect unusual system behavior, diagnose performance anomalies, and identify bottlenecks that can slow applications running on GPUs and other accelerator hardware. A key focus of the project is developing data-driven methods that can detect performance issues even when system data are noisy or incomplete, while also improving resource scheduling and overall system efficiency.
By helping maximize the use of valuable computing resources, these tools enable researchers to run simulations, data analyses, and AI workloads more effectively. BU Research Computing provides the large-scale computing environment, operational data, and infrastructure needed to develop and evaluate these techniques in real-world HPC systems.
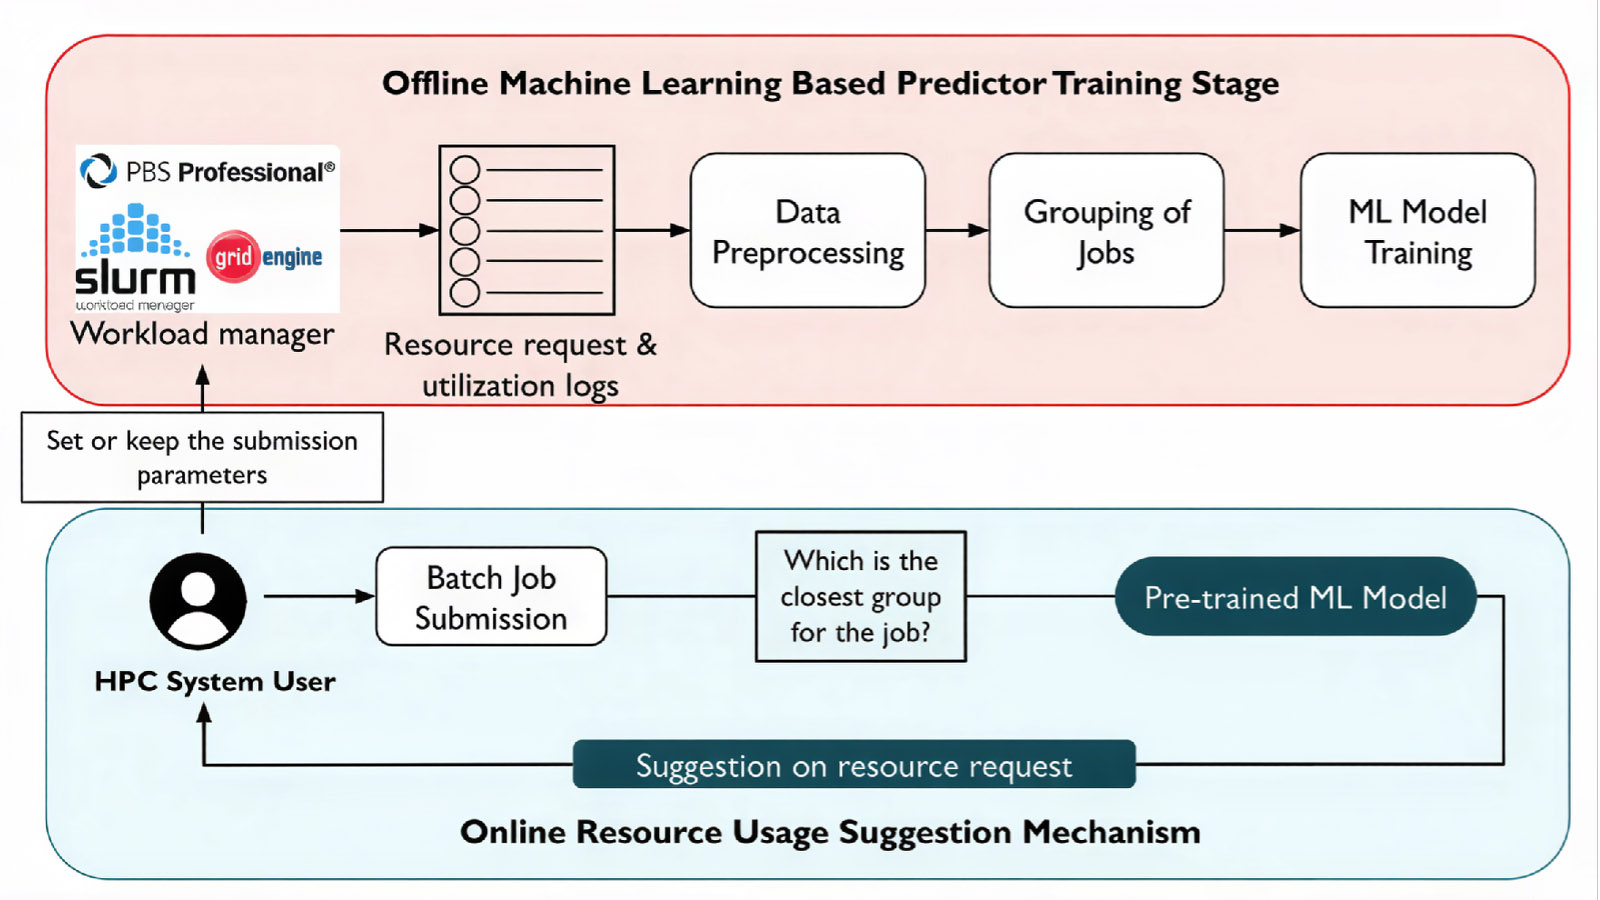
Beste Oztop, Benjamin Schwaller, Vitus J. Leung, Jim Brandt, Brian Kulis, Manuel Egele and Ayse K. Coskun (2025), Job Grouping Based Intelligent Resource Prediction Framework, 28th Workshop on Job Scheduling Strategies for Parallel Processing (JSSPP 2025), doi: 10.1007/978-3-032-10507-3_2
Efe Sencan, Yin-Ching Lee, Connor Casey, Benjamin Schwaller, Vitus J. Leung, Jim Brandt, Brian Kulis, Manuel Egele, and Ayse K. Coskun (2025), Refine: A Robust Approach to Unsupervised Anomaly Detection for Production HPC Systems, 2025 ISC High Performance Computing (ISC-HPC), doi: 10.23919/ISC.2025.11018307
Burak Aksar, Efe Sencan, Benjamin Schwaller, Omar Aaziz, Vitus J. Leung, Jim Brandt, Brian Kulis, Manuel Egele, and Ayse K. Coskun (2024), Runtime Performance Anomaly Diagnosis in Production HPC Systems Using Active Learning, in IEEE Transactions on Parallel and Distributed Systems (TPDS), doi: 10.1109/TPDS.2024.3365462
Burak Aksar, Efe Sencan, Benjamin Schwaller, Omar Aaziz, Vitus j. Leung, Jim Brandt, Brian Kulis, Manuel Egele, and Ayse K. Coskun (2023), Prodigy: Towards Unsupervised Anomaly Detection in Production HPC Systems, The International Conference on High Performance Computing, Network, Storage, and Analysis (SC 2023), doi: 10.1145/3581784.3607076
Burak Aksar, Efe Sencan, Benjamin Schwaller, Omar Aaziz, Vitus J. Leung, Jim Brandt, Brian Kulis, and Ayse K. Coskun (2022), ALBADross: Active Learning Based Anomaly Diagnosis for Production HPC Systems, in IEEE International Conference on Cluster Computing (Cluster), doi: 10.1109/CLUSTER51413.2022.00048
Burak Aksar, Yijia Zhang , Emre Ates, Benjamin Schwaller, Omar Aaziz, Vitus J. Leung, Jim Brandt, Manuel Egele, and Ayse K. Coskun (2021), Proctor: A Semi-Supervised Performance Anomaly Diagnosis Framework for Production HPC Systems, in International Supercomputing Conference (ISC-HPC), doi: 10.1007/978-3-030-78713-4_11
Ozan Tuncer, Emre Ates, Yijia Zhang, Ata Turk, Jim Brandt, Vitus J. Leung, Manuel Egele, and Ayse K. Coskun (2019), Online Diagnosis of Performance Variation in HPC Systems Using Machine Learning, in IEEE Transactions on Parallel and Distributed Systems (TPDS), doi: 10.1109/TPDS.2018.2870403